In the modern digital landscape, allowing software to “see” and interpret the physical world is no longer science fiction—it is a business necessity. From automating quality checks in manufacturing to moderating content and extracting text from millions of documents, computer vision is reshaping how we interact with data. Microsoft has positioned itself as a leader in this space, offering robust tools that democratize access to artificial intelligence.
If you have recently searched for aidemos microsoft com computer vision, you are likely curious about how Microsoft’s AI can analyze images and videos without requiring a PhD in data science. You might be a developer looking for integration specifics, a business owner exploring automation, or a student wanting to test the waters of AI.
This comprehensive guide will walk you through everything you need to know about Microsoft’s computer vision ecosystem. We will explore the official demonstration portals, the specific capabilities of the microsoft com AI suite, pricing breakdowns, and practical steps to start building your own intelligent systems today.
What is Microsoft Computer Vision? (An H2 Overview)
Before diving into demos and portals, it is crucial to understand the engine under the hood. Microsoft Computer Vision is a cloud-based service belonging to Azure AI (formerly known as Cognitive Services). It provides developers with access to advanced algorithms that process images and return information.
Unlike a standard database search that looks for metadata tags, Computer Vision uses machine learning models to recognize:
-
Objects and Scenery: Identifying specific items like “umbrella,” “car,” or “pizza,” as well as broader scenes like “beach” or “office.”
-
Text in Images (OCR): Extracting printed or handwritten text from screenshots, PDFs, or physical documents.
-
Faces: Detecting human faces and estimating attributes like age, emotion, and whether they are wearing glasses.
-
Brands and Landmarks: Automatically recognizing famous logos (Microsoft, Coca-Cola) or landmarks (Taj Mahal, Eiffel Tower).
The core value proposition here is accuracy at scale. A human can look at an image and describe it instantly, but a human cannot realistically do that for 10,000 images per minute. Microsoft Computer Vision bridges this gap with high-throughput processing.
Why Use Microsoft Over Others?
When discussing cloud vision services, the conversation often comes down to Microsoft vs. Google vs. Amazon. Each has unique strengths. Recent benchmarks comparing default API configurations show that Microsoft excels in specific niches, such as background removal and brand detection, while other tools might lead in specific retail tagging.
According to user reviews, professionals appreciate Microsoft’s integration capabilities—specifically, how easily the Vision service connects to other Azure tools like Logic Apps, Functions, and Power Platform. The ecosystem is a major selling point.
Exploring the aidemos microsoft com computer vision Portal
The most direct way to experience these capabilities without writing a single line of code is through the aidemos microsoft com computer vision portal. While many associate “AI demos” with specific generative AI tools, the core technology driving image understanding is often showcased in Microsoft’s official AI demo centers.
The aidemos subdomain historically acts as a showcase playground. For Computer Vision specifically, if you navigate to the appropriate demo section, you can:
-
Upload your own image (or paste an image URL).
-
Instantly see the AI analysis.
-
Compare results across different AI models.
Real-World Demo Scenario
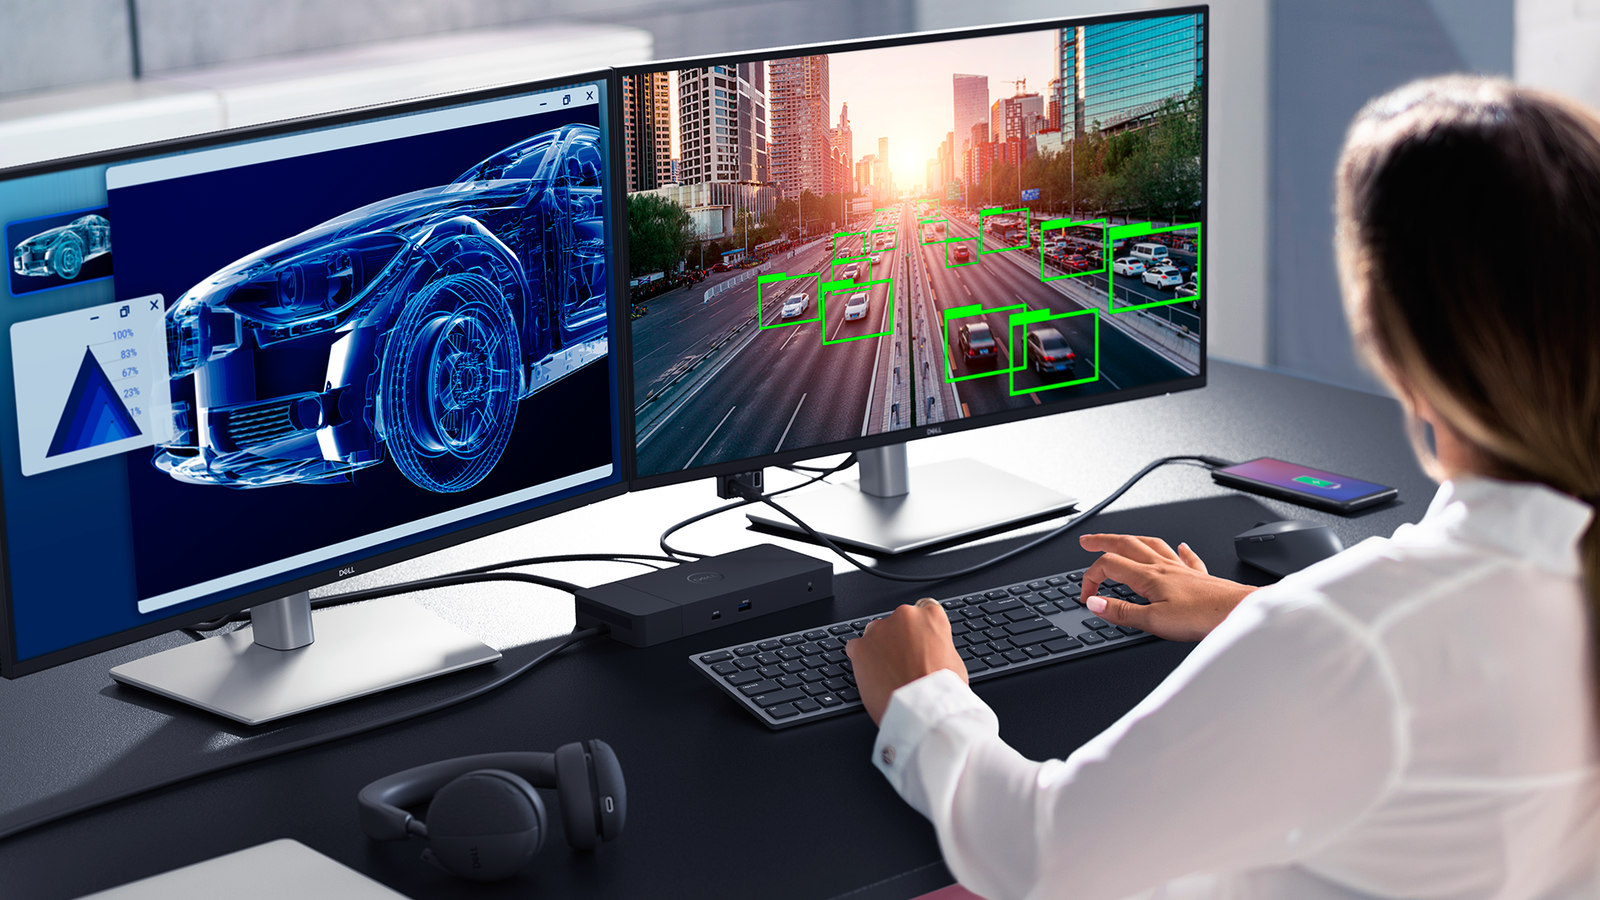
Imagine you upload a photo of a city street. Within milliseconds, the demo interface will likely return:
-
Tags: “Traffic,” “Car,” “Building,” “Asphalt,” “Pedestrian.”
-
Captions: “A busy city street with cars driving.”
-
Objects: Bounding boxes drawn around each car and person.
-
Text: Any text pulled from a storefront sign or a license plate.
This “try before you buy” approach lowers the barrier to entry significantly. You do not need to set up an Azure subscription just to see if the AI can read your specific handwriting. The demo serves as a proof of concept.
Breaking Down the Core Capabilities (H2)
While the demo gives you the “wow” factor, understanding the specific features helps you decide which part of the microsoft com ecosystem to use for your project. The service is typically divided into two main categories: Group 1 (Recognition) and Group 2 (Understanding).
H3: Optical Character Recognition (OCR) – The “Read” API
This is arguably the most used feature of Microsoft Computer Vision. The Read API is optimized for text-heavy documents and images.
-
Supports: Printed and handwritten text.
-
Languages: Over 160 languages.
-
Unique Feature: It preserves the layout of the document (tables, columns, text lines) so that when you extract the text, it remains in the correct reading order.
H3: Image Analysis (Captioning and Tagging)
This feature answers the question, “What is in this picture?” without needing a pre-defined database.
-
Tags: The AI generates a list of relevant keywords (e.g., “grass,” “dog,” “frisbee,” “outdoor”).
-
Captions: It generates a human-readable sentence. This is critical for accessibility (screen readers for the visually impaired) and for SEO of media files.
H3: Background Removal (Preview)
A newer, differentiating feature is the ability to automatically isolate the main subject of an image and remove the background. For e-commerce platforms, this is a game-changer. Instead of manually photoshopping product images, developers can use this API to create consistent white-background thumbnails instantly.
The Custom Vision Add-on
While the pre-trained models are powerful, what happens if you need to identify a specific widget on a factory line that wasn’t included in Microsoft’s general training data? This is where Custom Vision comes into play.
Custom Vision allows you to train the AI to recognize specific content.
How to train a Custom Vision model:
-
Upload Examples: You provide 5 to 10 images of your specific object (e.g., a broken engine part).
-
Label Them: You draw boxes or assign tags to the images (e.g., “Scratched” vs. “New”).
-
Train: The system uses transfer learning to build a specialized model quickly.
-
Test: Use the demo portal to test on a new image.